
 108
 0
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 www.xiaoyuzhoufm.com
【目录】
本期的 15 篇论文如下:
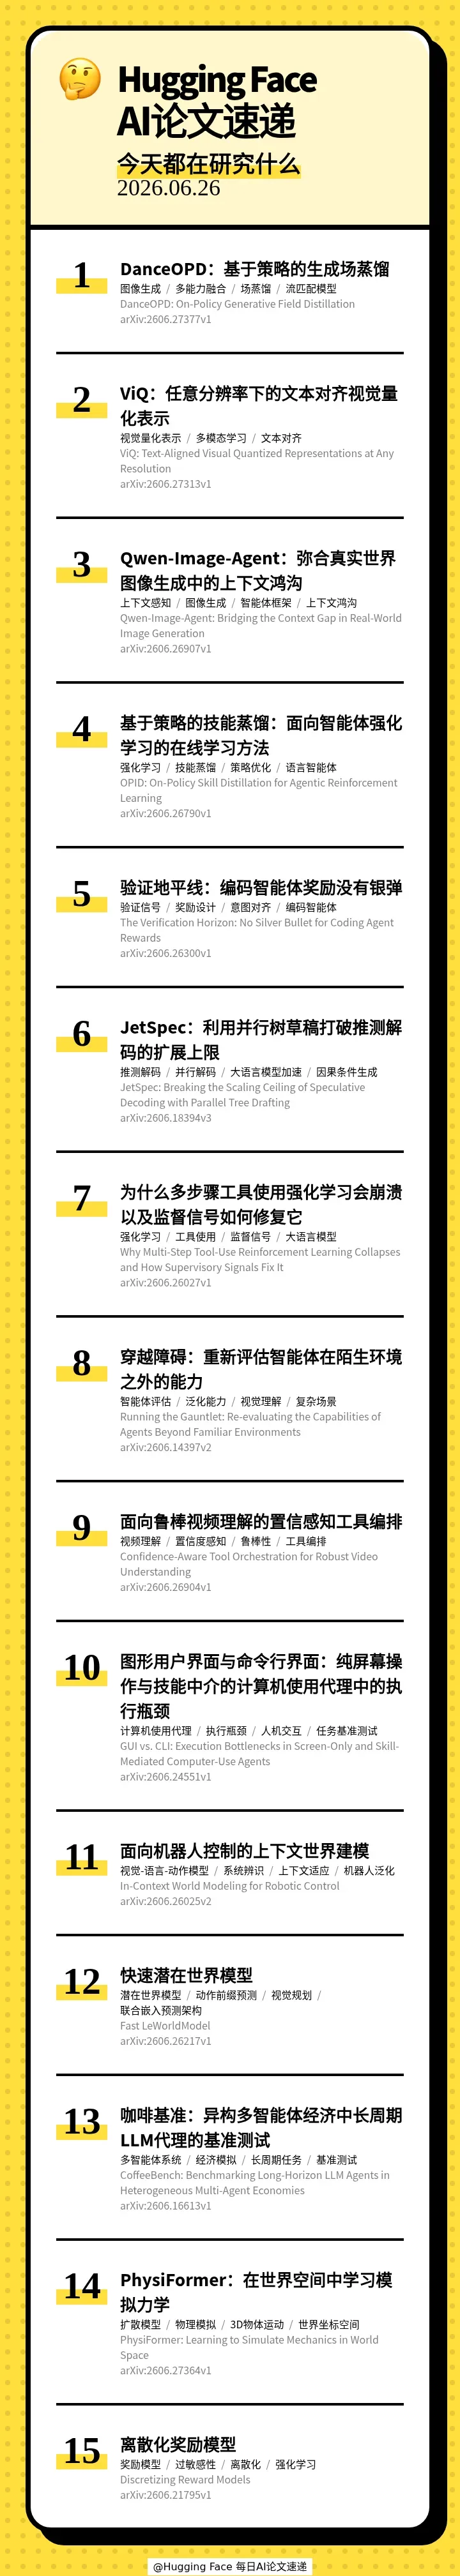
00:32 💃 DanceOPD: On-Policy Generative Field Distillation(DanceOPD:基于策略的生成场蒸馏)
01:34 🔍 ViQ: Text-Aligned Visual Quantized Representations at Any Resolution(ViQ:任意分辨率下的文本对齐视觉量化表示)
02:32 🎨 Qwen-Image-Agent: Bridging the Context Gap in Real-World Image Generation(Qwen-Image-Agent:弥合真实世界图像生成中的上下文鸿沟)
03:25 🤖 OPID: On-Policy Skill Distillation for Agentic Reinforcement Learning(基于策略的技能蒸馏:面向智能体强化学习的在线学习方法)
04:21 🔍 The Verification Horizon: No Silver Bullet for Coding Agent Rewards(验证地平线:编码智能体奖励没有银弹)
05:04 🚀 JetSpec: Breaking the Scaling Ceiling of Speculative Decoding with Parallel Tree Drafting(JetSpec:利用并行树草稿打破推测解码的扩展上限)
06:09 🛠 Why Multi-Step Tool-Use Reinforcement Learning Collapses and How Supervisory Signals Fix It(为什么多步骤工具使用强化学习会崩溃以及监督信号如何修复它)
06:57 🧩 Running the Gauntlet: Re-evaluating the Capabilities of Agents Beyond Familiar Environments(穿越障碍:重新评估智能体在陌生环境之外的能力)
07:50 🔍 Confidence-Aware Tool Orchestration for Robust Video Understanding(面向鲁棒视频理解的置信感知工具编排)
09:10 🖥 GUI vs. CLI: Execution Bottlenecks in Screen-Only and Skill-Mediated Computer-Use Agents(图形用户界面与命令行界面:纯屏幕操作与技能中介的计算机使用代理中的执行瓶颈)
10:11 🤖 In-Context World Modeling for Robotic Control(面向机器人控制的上下文世界建模)
10:59 🚀 Fast LeWorldModel(快速潜在世界模型)
11:47 ☕ CoffeeBench: Benchmarking Long-Horizon LLM Agents in Heterogeneous Multi-Agent Economies(咖啡基准:异构多智能体经济中长周期LLM代理的基准测试)
12:41 🧊 PhysiFormer: Learning to Simulate Mechanics in World Space(PhysiFormer:在世界空间中学习模拟力学)
13:34 🎲 Discretizing Reward Models(离散化奖励模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
