
 98
 0
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 www.xiaoyuzhoufm.com
【目录】
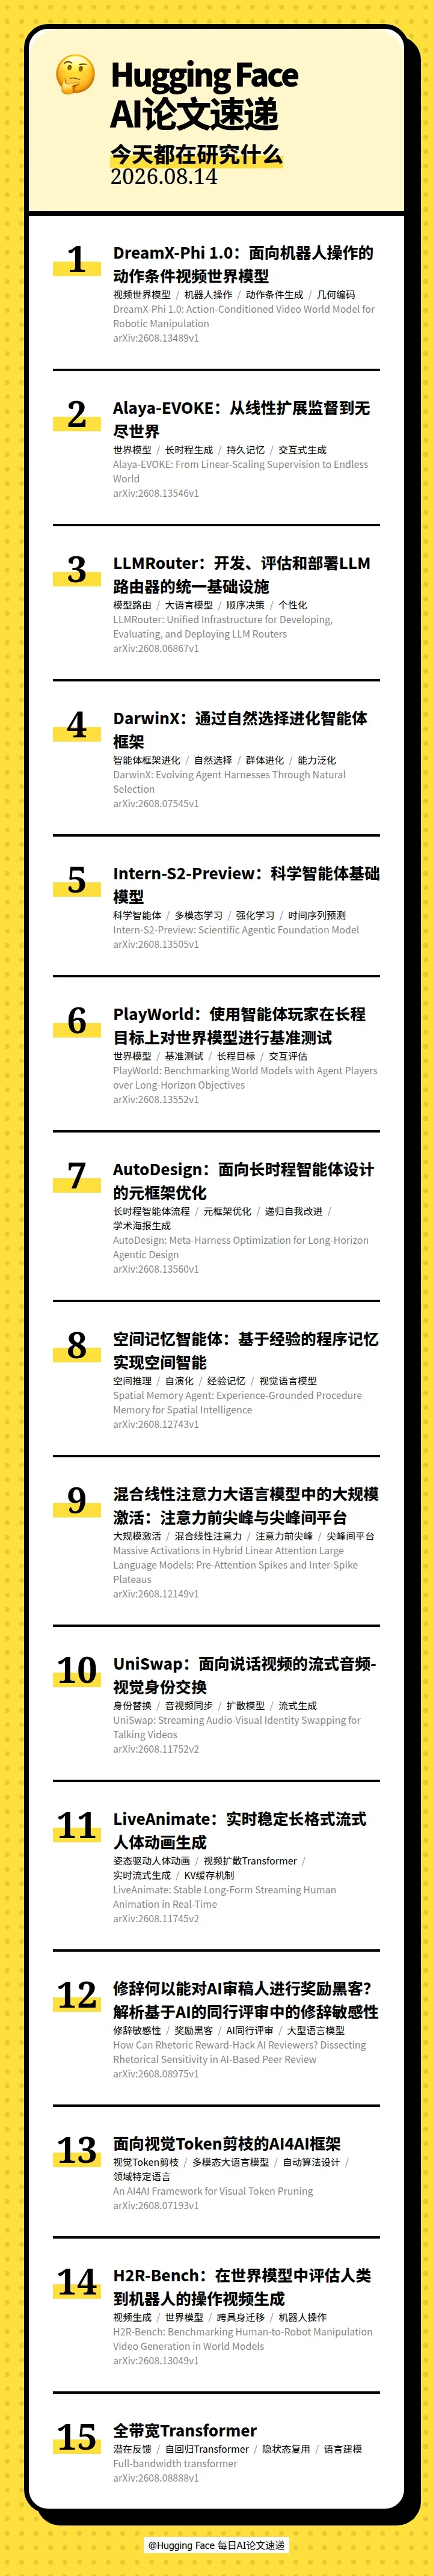
本期的 15 篇论文如下:
00:32 🤖 DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation(DreamX-Phi 1.0:面向机器人操作的动作条件视频世界模型)
01:24 🌍 Alaya-EVOKE: From Linear-Scaling Supervision to Endless World(Alaya-EVOKE:从线性扩展监督到无尽世界)
02:30 🔀 LLMRouter: Unified Infrastructure for Developing, Evaluating, and Deploying LLM Routers(LLMRouter:开发、评估和部署LLM路由器的统一基础设施)
03:25 🧬 DarwinX: Evolving Agent Harnesses Through Natural Selection(DarwinX:通过自然选择进化智能体框架)
04:26 🔬 Intern-S2-Preview: Scientific Agentic Foundation Model(Intern-S2-Preview:科学智能体基础模型)
05:20 🎮 PlayWorld: Benchmarking World Models with Agent Players over Long-Horizon Objectives(PlayWorld:使用智能体玩家在长程目标上对世界模型进行基准测试)
06:20 🤖 AutoDesign: Meta-Harness Optimization for Long-Horizon Agentic Design(AutoDesign:面向长时程智能体设计的元框架优化)
07:23 🧠 Spatial Memory Agent: Experience-Grounded Procedure Memory for Spatial Intelligence(空间记忆智能体:基于经验的程序记忆实现空间智能)
08:12 ⚡ Massive Activations in Hybrid Linear Attention Large Language Models: Pre-Attention Spikes and Inter-Spike Plateaus(混合线性注意力大语言模型中的大规模激活:注意力前尖峰与尖峰间平台)
09:03 🎭 UniSwap: Streaming Audio-Visual Identity Swapping for Talking Videos(UniSwap:面向说话视频的流式音频-视觉身份交换)
10:12 ⚡ LiveAnimate: Stable Long-Form Streaming Human Animation in Real-Time(LiveAnimate:实时稳定长格式流式人体动画生成)
11:08 🤖 How Can Rhetoric Reward-Hack AI Reviewers? Dissecting Rhetorical Sensitivity in AI-Based Peer Review(修辞何以能对AI审稿人进行奖励黑客?解析基于AI的同行评审中的修辞敏感性)
12:00 ✂ An AI4AI Framework for Visual Token Pruning(面向视觉Token剪枝的AI4AI框架)
12:56 🤖 H2R-Bench: Benchmarking Human-to-Robot Manipulation Video Generation in World Models(H2R-Bench:在世界模型中评估人类到机器人的操作视频生成)
14:08 🔄 Full-bandwidth transformer(全带宽Transformer)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
