
 1
 0
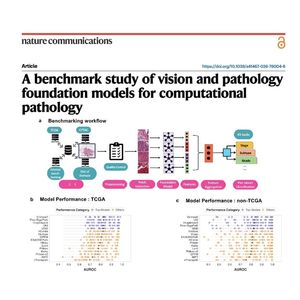
This research paper details PathBench, a massive benchmarking study that evaluates 32 artificial intelligence foundation models to determine their effectiveness in computational pathology. The authors categorized these AI tools into four groups based on whether they were trained on general vision or pathology-specific data, and whether they utilized textual language integration. By testing these models across 41 diverse clinical tasks and more than 17,500 whole-slide images, the study identifies which architectures best generalize across different cancer types and datasets. A key finding is that pathology-specific vision models generally outperform multimodal language models, though increasing the size of a model or its training data does not always guarantee better results. Ultimately, the researchers demonstrate that ensembling, or combining the predictions of multiple top-performing models, provides the most stable and robust performance for precision medicine applications.
References:
Bareja R, Carrillo-Perez F, Zheng Y, et al. A benchmark study of vision and pathology foundation models for computational pathology[J]. Nature Communications, 2026.
