
 103
 0
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 www.xiaoyuzhoufm.com
【目录】
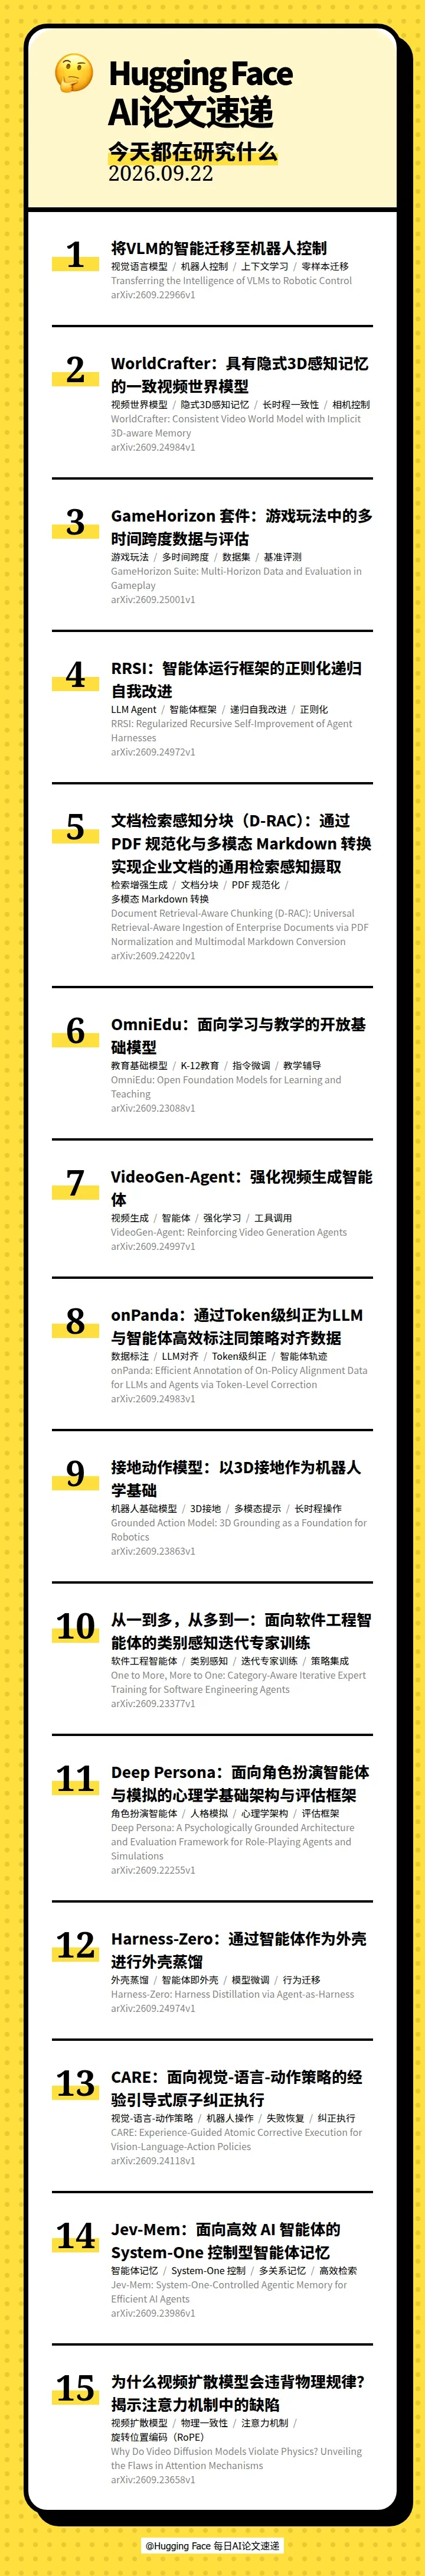
本期的 15 篇论文如下:
00:28 🤖 Transferring the Intelligence of VLMs to Robotic Control(将VLM的智能迁移至机器人控制)
01:11 🎥 WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory(WorldCrafter:具有隐式3D感知记忆的一致视频世界模型)
01:53 🎮 GameHorizon Suite: Multi-Horizon Data and Evaluation in Gameplay(GameHorizon 套件:游戏玩法中的多时间跨度数据与评估)
02:35 🧬 RRSI: Regularized Recursive Self-Improvement of Agent Harnesses(RRSI:智能体运行框架的正则化递归自我改进)
03:20 📄 Document Retrieval-Aware Chunking (D-RAC): Universal Retrieval-Aware Ingestion of Enterprise Documents via PDF Normalization and Multimodal Markdown Conversion(文档检索感知分块(D-RAC):通过 PDF 规范化与多模态 Markdown 转换实现企业文档的通用检索感知摄取)
04:01 🎓 OmniEdu: Open Foundation Models for Learning and Teaching(OmniEdu:面向学习与教学的开放基础模型)
04:47 🎬 VideoGen-Agent: Reinforcing Video Generation Agents(VideoGen-Agent:强化视频生成智能体)
05:37 🐼 onPanda: Efficient Annotation of On-Policy Alignment Data for LLMs and Agents via Token-Level Correction(onPanda:通过Token级纠正为LLM与智能体高效标注同策略对齐数据)
06:19 🤖 Grounded Action Model: 3D Grounding as a Foundation for Robotics(接地动作模型:以3D接地作为机器人学基础)
07:05 🤖 One to More, More to One: Category-Aware Iterative Expert Training for Software Engineering Agents(从一到多,从多到一:面向软件工程智能体的类别感知迭代专家训练)
07:57 🎭 Deep Persona: A Psychologically Grounded Architecture and Evaluation Framework for Role-Playing Agents and Simulations(Deep Persona:面向角色扮演智能体与模拟的心理学基础架构与评估框架)
08:36 🧠 Harness-Zero: Harness Distillation via Agent-as-Harness(Harness-Zero:通过智能体作为外壳进行外壳蒸馏)
09:18 🤖 CARE: Experience-Guided Atomic Corrective Execution for Vision-Language-Action Policies(CARE:面向视觉-语言-动作策略的经验引导式原子纠正执行)
10:13 🧠 Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents(Jev-Mem:面向高效 AI 智能体的 System-One 控制型智能体记忆)
10:52 🎥 Why Do Video Diffusion Models Violate Physics? Unveiling the Flaws in Attention Mechanisms(为什么视频扩散模型会违背物理规律?揭示注意力机制中的缺陷)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
