
 0
 0
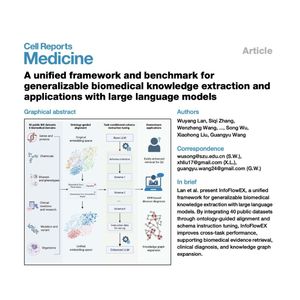
Researchers introduce InfoFlowEX, a unified framework designed to improve how large language models (LLMs) extract structured data from complex biomedical text. The system addresses the inconsistency of existing resources by using ontology-guided alignment to merge 40 diverse datasets into a massive, standardized benchmark called BIE-Corpus. To improve performance, the authors utilize task-conditioned schema instruction tuning, which uses code-based representations to help models adapt to specific extraction requirements. Evaluation across various models proves that this method significantly enhances accuracy in named entity recognition and relation extraction. Beyond basic data processing, the framework shows practical utility in clinical diagnosis from health records, evidence retrieval for medical queries, and the expansion of knowledge graphs. Ultimately, InfoFlowEX provides a scalable solution for transforming unstructured scientific literature and clinical notes into computable, reusable knowledge.
References:
Lan W, Zhang S, Wang W, et al. A unified framework and benchmark for generalizable biomedical knowledge extraction and applications with large language models[J]. Cell Reports Medicine, 2026, 7(8).
